How to extract tables from a PDF to Excel
A PDF table describes positions on a page, not necessarily spreadsheet cells. Conversion must reconstruct that organization, so opening the XLSX without an error is only the first review step.
Steps and checks
- Select your file in PDF to Excel and choose One sheet per table to review separate datasets.
- Use Combine all tables only when joining them makes sense. Check that headers and columns represent the same data.
- Keep OCR enabled if the file includes scanned tables. Small text, faint lines, and tilted pages can affect recognition.
- Open the spreadsheet, compare the record count, and check rows from the beginning, middle, and end of each table.
Which values become numbers?
The converter recognizes decimal-comma amounts in clearly numeric columns such as Amount or Total, within the supported precision limit. Codes, identifiers, and dates remain text; ambiguous entries may also remain text. PDF content is not turned into formulas. Check each column type before calculating.
Decimal separators and dates
1.234,56 and 1,234.56 can represent the same value in different conventions. A date such as 03/04 is also ambiguous. Use the correct locale when importing or converting columns; do not replace every comma and period indiscriminately.
Merged cells and repeated headers
A title spanning several columns may be interpreted as an individual cell. Headers repeated on each page may appear between records. Check both before summing or filtering. A similar appearance does not guarantee that values are in the correct columns.
Minimum checks before using the data
Compare row counts, identify empty or shifted columns, and check totals using the original document rules. The tool does not restore formulas from the spreadsheet that produced the PDF. Results depend on file structure and quality; keep the original.
Checked example: six records and five columns
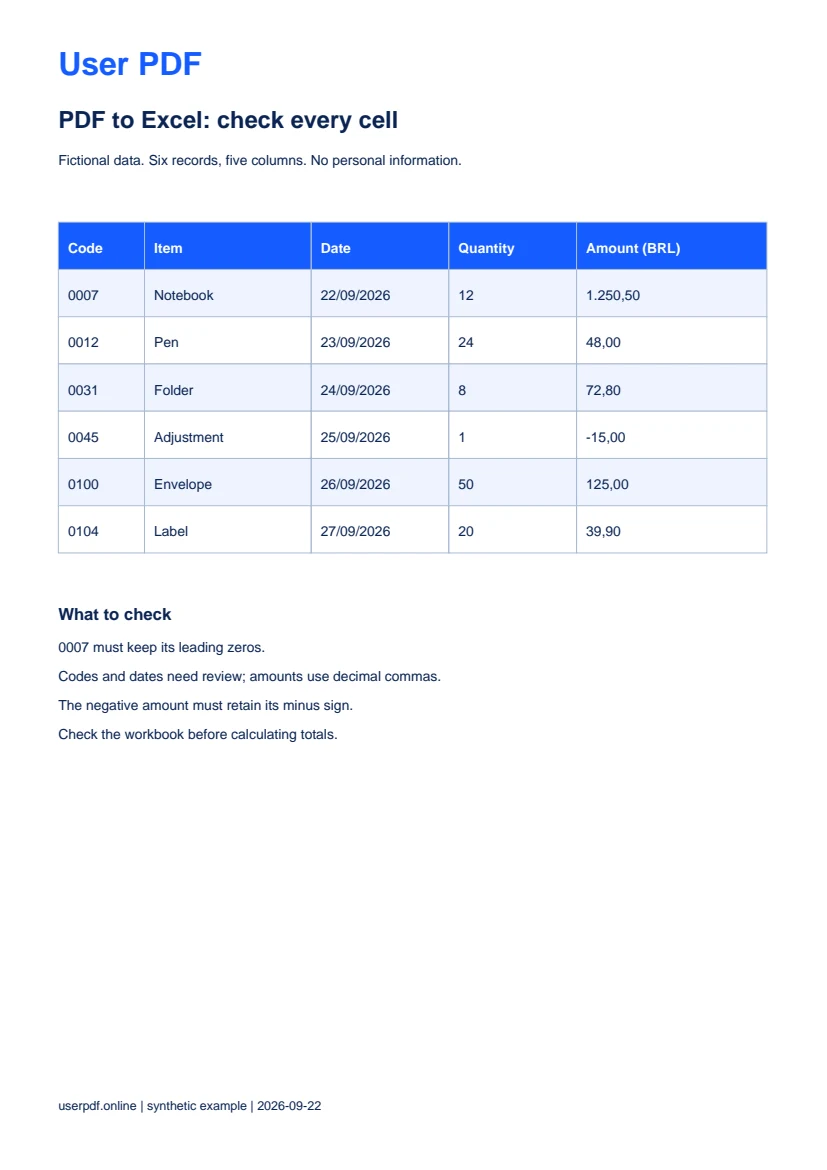
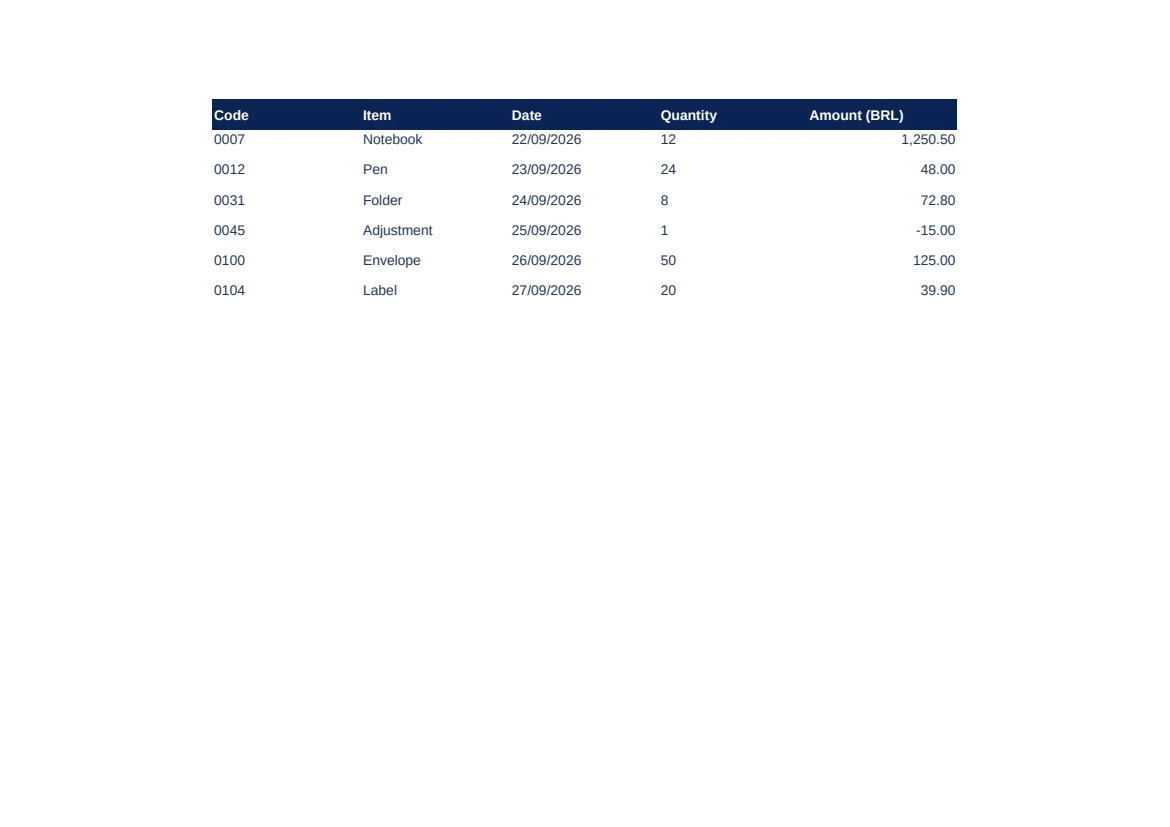
On September 22, 2026, we converted a fictional native-text PDF using One sheet per table with OCR available. All 30 data cells and five headers matched the expected values. Code 0007 retained its zeros, -15,00 became numeric -15, and dates remained text. The workbook contains one table and a Contexto sheet for surrounding text. This simple example does not measure accuracy on other documents.
How to reproduce and interpret the preview
Download the sample PDF and upload it to PDF to Excel with the settings above. Compare records, cell types, and the Contexto sheet against the published workbook. The preview shows the first page of the actual XLSX reopened in LibreOffice, without restyling for this demonstration. Its rendered PDF has two pages. Displayed separators depend on your editor locale; the sample uses BRL amounts and day/month/year dates. Downloading examples uses no allowance; running a new conversion uses one operation.
PDF to Excel: a verifiable result
| Check | Observed result |
|---|---|
| Records and columns | 6 records × 5 columns |
| Cells checked | 30 data cells + 5 headers, all matching |
| Code with leading zeros | 0007 preserved as text |
| Data types | 6 numeric amounts; 24 text cells |
| Text outside the table | Preserved in the Contexto sheet |
| Pages when reopened | 1 input PDF page; 2 pages in the rendered XLSX |